
Basalt
Docker app from MadeOfCard's Repository
Basalt runs large language models on an NVIDIA Blackwell GPU plus system RAM: Qwen3.8-Flash-Next, DeepSeek-V4.1-Flash and the dense Qwen3.8-27B.
Requirements
Nvidia Driver plugin on driver 580 or newer and an RTX 50 series (Blackwell) card. A basalt_config.json in the AppData folder (see the Overview). Do not set a memory limit on the container: Basalt plans from the server's free RAM.
Overview
Basalt runs large language models on an NVIDIA Blackwell GPU plus system RAM: Qwen3.8-Flash-Next, DeepSeek-V4.1-Flash and the dense Qwen3.8-27B. The experts of a mixture-of-experts model that do not fit in graphics memory are kept in RAM. It serves an OpenAI- and Anthropic-compatible API and a chat page. This template runs an image built from Basalt's own Dockerfile.
Requirements: the Nvidia Driver plugin on driver 580 or newer and an RTX 50 series (Blackwell) card; older cards are not supported. You also need room for the model on an SSD pool and enough RAM for the part of the model that does not fit on the card.
Choosing a model: a model is one .basalt file. Download it into the Models folder from the Unraid terminal, for example:
wget -c -P /mnt/cache/appdata/basalt/models https://huggingface.co/jesdga/Qwen3.8-27B-Basalt/resolve/main/Qwen3.8-27B-QUASAR-NVFP4.basalt
(-c resumes a stopped download). The sizes below are the download.
Qwen3.8-Flash-Next, the main model, for chat, code and tools (huggingface.co/jesdga/Qwen3.8-Flash-Next-Basalt):
- Qwen3.8-FN-NVFP4-DQ6_K: the default. 132 GB.
- Qwen3.8-FN-UD-IQ1_S, UD-IQ1_M, UD-IQ2_XS, UD-IQ3_XXS: smaller, for less RAM, at some cost in quality. 70-88 GB.
- Qwen3.8-FN-UD-IQ4_XS, UD-Q4_K_XL, UD-Q5_K_XL, UD-Q6_K_XL, Q8_0: more bits, for servers with a lot of RAM. 98-192 GB.
Qwen3.8-27B, a dense model that runs on the card alone (huggingface.co/jesdga/Qwen3.8-27B-Basalt):
- Qwen3.8-27B-QUASAR-NVFP4: 21 GB.
DeepSeek-V4.1-Flash, the largest model (huggingface.co/jesdga/DeepSeek-V4.1-Flash-1017-Basalt):
- DeepSeek-V4.1-Flash-1017-UD-IQ1_M: the default. 260 GB.
- UD-IQ2_XXS: 286 GB. NVFP4: 428 GB.
Config file: Basalt reads its settings from basalt_config.json in the AppData folder and does not start without it. Name the model by its path inside the container (/models/...), and keep server.port at 8080. A minimal file:
{"version": 2, "models": [{"model": "/models/Qwen3.8-FN-NVFP4-DQ6_K.basalt", "kv": "int8", "max-context": 32768}], "engine": {"resident-experts": true}, "server": {"port": 8080}}
The context defaults to 8,192 tokens. To open the chat page by a host name (tower.local) rather than the server's IP, add "allowed-host": ["tower.local"] to the server block. Every setting: docs/configuration in the Basalt repository.
First start: the page is up at once and the model loads behind it, with the progress shown in the page header; watch the log. A failed load stops the container and the log says why.
API key: Basalt takes the key on the command line only, not in the config file. Without one the API is open to your network. To set one, switch to Advanced View and enter --api-key KEY in Post Arguments (openssl rand -hex 24 makes one). Clients send it as Authorization: Bearer KEY or x-api-key.
Changing settings: edit basalt_config.json and restart the container. The model files stay in the Models folder.
Template and Unraid problems: the Support link. Basalt itself: the Project link.
Readme
View on GitHub
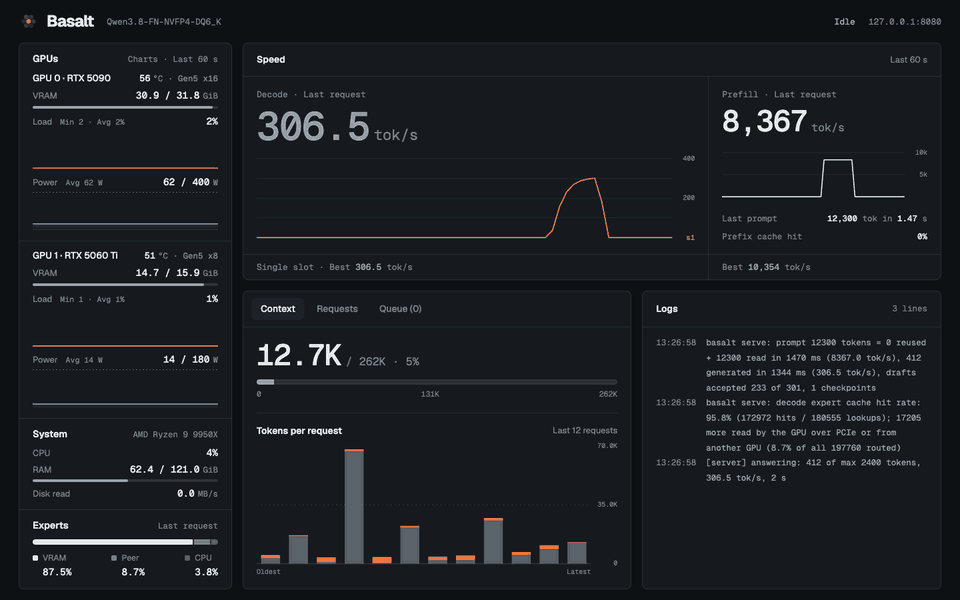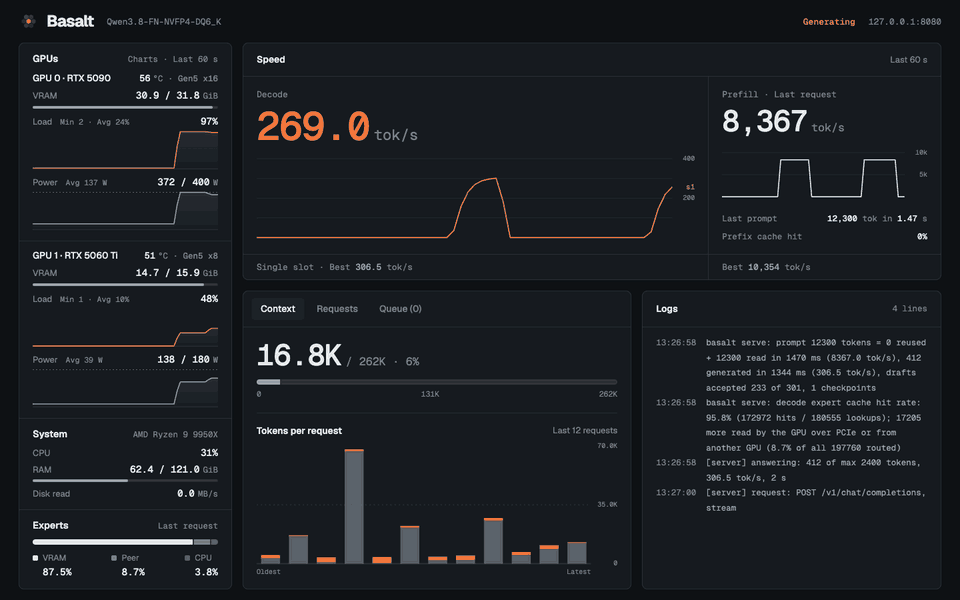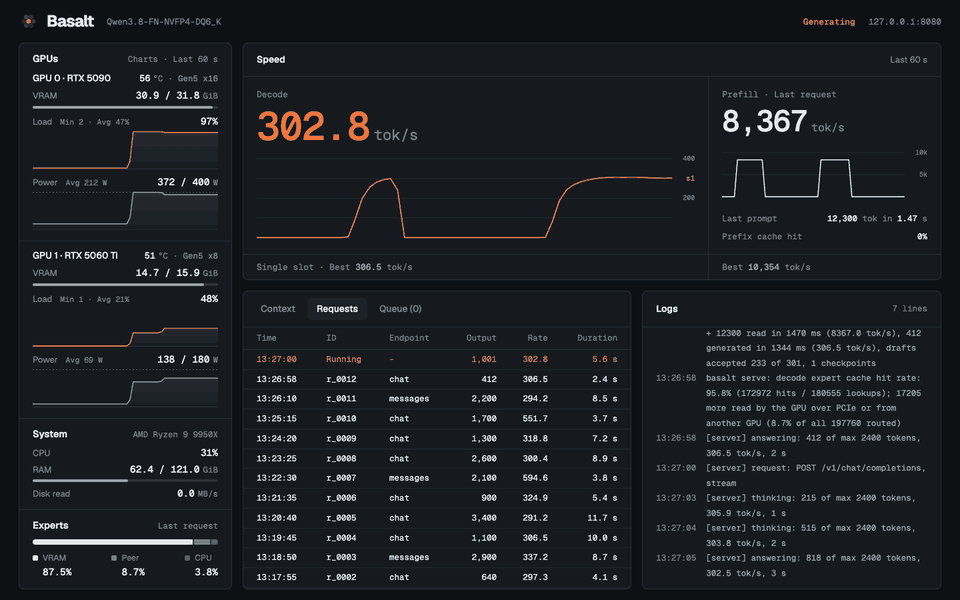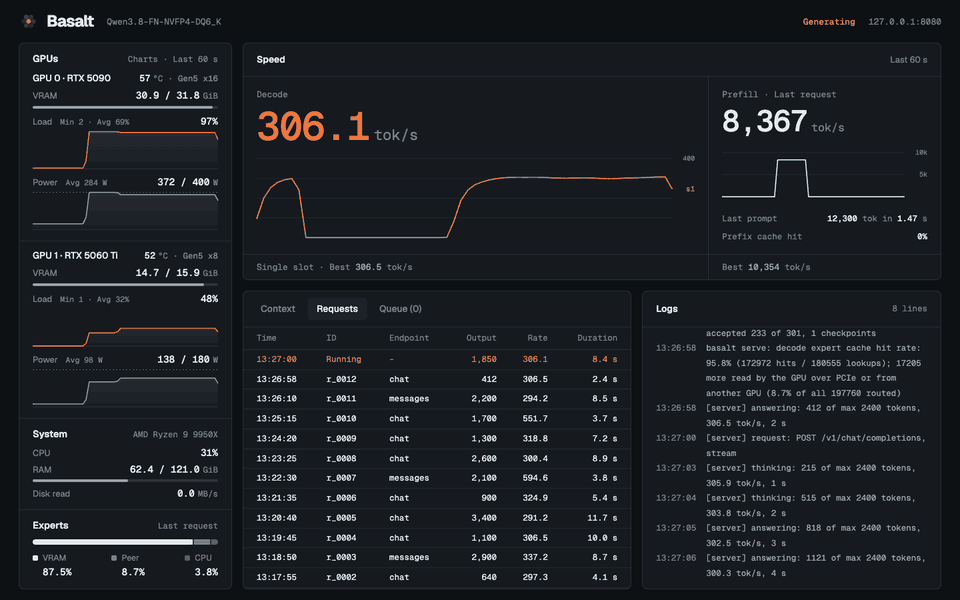
Basalt is a local inference engine for large language models: Qwen3.8-Flash-Next, DeepSeek-V4.1-Flash and Qwen3.8-27B. It runs on an NVIDIA Blackwell GPU (sm_120) on Linux and Windows x64, with what does not fit in VRAM (the experts of a mixture-of-experts model) in system RAM, and optionally on more GPUs. The server speaks the OpenAI and Anthropic APIs. Website: basalt.jgulfo.com.
Help wanted: spare Blackwell compute for testing? See Contributing.
Requirements
- Linux x86-64 with AVX2, or Windows 10 1903+ x64 (platforms).
- An NVIDIA Blackwell GPU (compute capability 12.0) with CUDA 13.
- CMake 3.24+, GCC 13+ (Linux), Python 3.10+, and enough system RAM for the experts that do not fit in VRAM.
Quick start
Prebuilt Linux and Windows archives are attached to each release (what they need); otherwise build from source:
git clone https://github.com/jesdga95/basalt && cd basalt
cmake -S . -B build -DCMAKE_BUILD_TYPE=Release
cmake --build build -j                  # bin/basalt, bin/basalt-bench, bin/basalt-probe, bin/basalt-vision
                                        # Windows: add -G Ninja to the first line, from an x64 VS 2022 prompt ([platforms](docs/platforms.md#building-on-windows))
                                        # one model only: -DBASALT_MODELS=qwen4exp, deepseek41 or qwen35 ([building](docs/building.md#building-only-some-models))
pip install -r requirements.txt
hf download jesdga/Qwen3.8-Flash-Next-Basalt Qwen3.8-FN-NVFP4-DQ6_K.basalt --local-dir models
Put the settings in basalt_config.json:
{
  "version": 2,
  "models": [{ "model": "models/Qwen3.8-FN-NVFP4-DQ6_K.basalt", "gpu": "0,1", "kv": "int8" }],
  "engine": { "resident-experts": true },
  "server": { "port": 8080 }
}
bin/basalt serve --config basalt_config.json
The server listens on 127.0.0.1. Every setting: configuration. More examples: example configurations.
Models
| Qwen3.8-Flash-Next | DeepSeek-V4.1-Flash | Qwen3.8-27B | |
|---|---|---|---|
| Packs | default Qwen3.8-FN-NVFP4-DQ6_K, Hugging Face |
default DeepSeek-V4.1-Flash-1017-UD-IQ1_M, Hugging Face |
Qwen3.8-27B-QUASAR-NVFP4, Hugging Face |
| Context | up to 262,144 (longer with YaRN) | up to 1,048,576 | up to 262,144 |
| Drafting | MTP, on by default | DSpark, on by default | DFlash 2, on by default |
| Images | yes | yes | yes |
| Documents (PDF, text) | yes | yes | yes |
| Guide | guide | guide | guide |
| Precision | precision | precision | precision |
All models compared, with each one's context limit, flags and cards: models.
Video
Qwen3.8-Flash-Next and Qwen3.8-27B read video; DeepSeek does not. A video is named like an image in a chat message, and needs
--vision and FFmpeg on the machine. Flash-Next decodes frames on the GPU with NVDEC; the 27B decodes them on the CPU.
How a request names a video, and the limits: video.
Documentation
- Run: running, configuration, models and the router, sampling, image sources, documents, diagnostics, basalt-probe, platforms.
- Models: models, Flash-Next, DeepSeek,
Qwen3.8-27B,
the
.basaltfile, file format changes. - Quality: precision, method.
- Build and develop: building, adding a model, community runs, changelog, contributing.
Credits
- Code: Strata, the project Basalt forks (MIT); Infernix (Ian Ranson and contributors, Apache-2.0), whose kernels are adapted; ggml and llama.cpp (MIT); and ideas from NInfer. Licences: THIRD_PARTY_LICENSES.
- Models: Qwen and DeepSeek, under the licences on their cards; Unsloth's GGUFs; NVIDIA's NVFP4 checkpoints; QUASAR-QAT's NVFP4 27B (Apache-2.0); z-lab's DFlash 2 drafter.
Thank you to everyone who has contributed or sponsored the project.
License
MIT, see LICENSE.
Categories
Related apps
Explore more like this
Explore allLinks
Details
ghcr.io/williamkunz/basalt:latestRuntime arguments
- Web UI
http://[IP]:[PORT:8080]/- Network
bridge- Shell
bash- Privileged
- false
- Extra Params
--runtime=nvidia --ulimit memlock=-1:-1 --shm-size=2g --stop-timeout 120
Template configuration
Chat page and the API (/v1 for OpenAI clients, the root URL for Anthropic clients). Keep server.port in basalt_config.json at 8080; change the host port here instead.
- Target
- 8080
- Default
- 8080
- Value
- 8080
Holds basalt_config.json, and the server's engine log and conversation disk tier under .cache/basalt.
- Target
- /data
- Default
- /mnt/cache/appdata/basalt
- Value
- /mnt/cache/appdata/basalt
The .basalt model files: 21 GB for Qwen3.8-27B, 70 to 192 GB for Flash-Next, 260 GB or more for DeepSeek. Name them in the config as /models/FILE.basalt. Use a direct pool path on an NVMe drive (/mnt/cache/... or /mnt/POOLNAME/...), not /mnt/user: the engine reads the model files while it runs.
- Target
- /models
- Default
- /mnt/cache/appdata/basalt/models
- Value
- /mnt/cache/appdata/basalt/models
The cards the container sees: a UUID (GPU-xxxxxxxx-...) from the Nvidia Driver plugin page or nvidia-smi -L, several separated by commas, or all. A gpu value in basalt_config.json counts only the cards listed here, from 0.
- Target
- NVIDIA_VISIBLE_DEVICES
- Default
- all
- Value
- all
Driver features the container gets. compute,utility is enough for Basalt.
- Target
- NVIDIA_DRIVER_CAPABILITIES
- Default
- compute,utility
- Value
- compute,utility